A critical vulnerability on an unused test server and a lower-severity weakness affecting a patient-records service should not receive the same response. Yet many security teams still work from queues that treat them as broadly equivalent. Business context risk scoring changes that equation by connecting technical findings to the services, people, data and operational outcomes that matter most.
The objective is not to produce another risk score for a dashboard. It is to give leaders a defensible answer to a harder question: what needs fixing first, why does it matter, and what is the exposure if it is left unresolved?
Why technical severity is not enough
Severity ratings remain useful. They indicate the potential impact of a vulnerability or misconfiguration under defined conditions. But they do not show whether the affected asset is live, internet-facing, part of a critical business service, protected by compensating controls or owned by a team able to act quickly.
That missing context is where prioritisation breaks down. A vulnerability score may be high, while the real-world risk is limited because the system is isolated and scheduled for retirement. Conversely, a medium-rated configuration issue may sit on an identity platform, payment service or operational technology environment where disruption would be commercially or operationally significant.
A technical queue tells security teams what has been found. A business-context model tells the organisation what that finding could affect. The distinction matters when remediation capacity is finite, audit deadlines are approaching and leadership needs confidence that cyber investment is reducing meaningful risk.
What business context risk scoring should measure
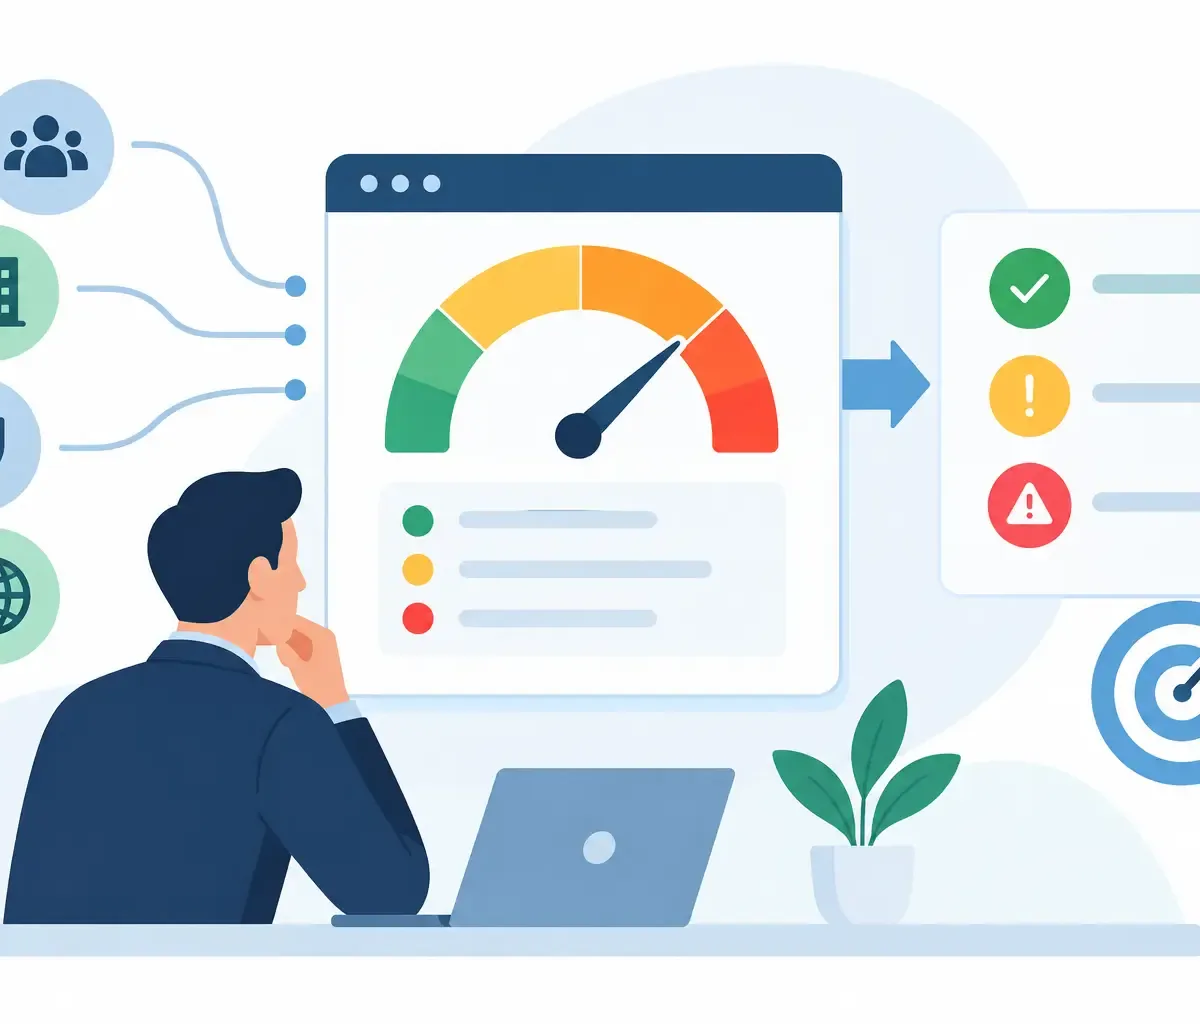
Effective scoring combines evidence from across the environment rather than relying on a single feed. The precise model will vary by organisation, but it should account for the relationship between an asset, its exposure and the service it supports.
Asset and service criticality
An asset should not be considered in isolation. A domain controller, cloud workload, Microsoft 365 tenant configuration or Kubernetes cluster may underpin multiple services. The score needs to reflect the criticality of those services, whether they support revenue, citizen services, patient care, regulated data or essential internal operations.
This requires a reliable service model. If teams cannot identify which infrastructure supports a business process, they cannot explain impact with confidence. Service ownership also matters. A score is more useful when it identifies the accountable owner and the route to remediation, rather than simply raising an alert against an IP address or hostname.
Exposure and reachability
Risk changes according to who can reach an asset and how. Internet exposure, privileged access paths, lateral movement opportunities and dependencies on shared identity services all increase urgency. Internal-only does not automatically mean safe, particularly where a compromise could spread through poorly segmented networks or trusted administrative relationships.
The key is to distinguish theoretical exposure from an actionable attack path. A finding that is exploitable, exposed and connected to a critical service warrants a different response from the same finding in a contained environment with no viable route to sensitive systems.
Control strength and evidence
A risk score should recognise the controls already in place. Multi-factor authentication, secure configuration, network segmentation, endpoint protection, monitored privileged access and effective backup arrangements can reduce the likelihood or impact of an event. They do not remove the need to fix underlying weaknesses, but they can inform a rational remediation order.
This is also where continuous evidence matters. A policy document saying a control exists is not the same as evidence that it is working across the relevant estate. Current configuration, identity and asset data give security leaders a more accurate position than annual attestations or manually assembled spreadsheets.
Data, regulatory and operational impact
The impact of compromise is not limited to data loss. Consider legal and contractual obligations, service availability, safety, recovery effort, reputational consequences and the cost of delayed operations. A public-sector service with a large user base may have a different impact profile from a commercial platform with a smaller number of high-value customers. Both may be critical, but for different reasons.
Scoring models should make these distinctions visible. A single numerical value is helpful for ordering work, but the supporting rationale must remain clear enough for a service owner, auditor or board member to understand.
Build a scoring model people will trust
The most effective models are practical. They use data the organisation can maintain, avoid false precision and can be explained without a security glossary. If the methodology is too complex to challenge or calibrate, teams will work around it.
Start by defining a small set of business impact tiers. For example, a service might be classified as critical, high, standard or low based on customer impact, regulatory requirements, financial dependency and recovery tolerance. Then map known assets, identities, cloud resources and infrastructure components to those services.
Next, combine that service classification with technical evidence: vulnerability severity, active exposure, exploitability, configuration posture, privileged access and control coverage. Apply clear rules for exceptions. A compensating control may reduce urgency, but it should have an owner, an expiry date and evidence that it remains effective.
Finally, review the results with operational teams. Security may understand the technical condition of a platform, while service owners understand the consequences of disruption. Both perspectives are required. This review often exposes gaps in asset ownership, service maps and recovery assumptions that need attention in their own right.
Avoid the common scoring failures
Contextual scoring can fail when it becomes a one-off classification exercise. Infrastructure changes, cloud services scale, identities gain privileges and business processes move. Static criticality labels soon become misleading. The model must be refreshed as the environment changes.
Another failure is treating every item connected to a critical service as equally urgent. A supporting development system may need attention, but its risk will differ from a production asset that directly processes sensitive data. Dependency knowledge should sharpen prioritisation, not create an unmanageable list of critical alerts.
Teams should also resist scoring based on incomplete discovery. Unknown assets, unmanaged accounts and unmonitored cloud resources are not neutral. They are gaps in assurance. A mature approach highlights uncertainty so leaders can fund discovery and validation work, rather than assuming the inventory is complete.
Turn scores into operational decisions
A score only earns its place if it changes what people do. Security operations need prioritised remediation work with clear asset, service and ownership details. IT teams need to know whether a fix is urgent, what change window is acceptable and which business dependency could be affected. Executives need trend information that shows whether exposure in critical services is falling.
This is where a consolidated platform has an advantage over fragmented tooling. Bringing together asset intelligence, vulnerabilities, secure configuration, identity visibility and service context reduces the manual effort required to assemble a credible risk picture. It also makes it easier to show evidence before, during and after remediation.
For MSPs and MSSPs, the same principle applies across customer environments. A long list of alerts is difficult to package as a managed service. Prioritised service risk, backed by current evidence and clear remediation recommendations, creates a more valuable conversation with customers and a more scalable operating model.
Rebasoft supports this approach by providing agentless, scanless visibility across connected environments and relating technical conditions to the business services they support. The result is not simply better reporting. It is faster decisions based on evidence that operational teams and leadership can both use.
Measure whether prioritisation is working
Do not judge the programme by the number of alerts closed alone. Track the time taken to remediate issues affecting critical services, the number of unknown or unowned assets, control coverage across high-impact environments and the ageing of accepted risks. These measures show whether the organisation is reducing material exposure or merely processing tickets.
Board reporting should follow the same discipline. Report changes in the risk position of key services, the controls validated, the exceptions accepted and the decisions required. This gives leadership answers they can trust without forcing them to interpret raw vulnerability data.
The useful question is not, “How many findings do we have?” It is, “Which business services are most exposed, what evidence supports that view, and what action will reduce the risk now?” When the organisation can answer that consistently, risk scoring becomes a mechanism for resilience rather than another source of noise.