A NIST CSF implementation guide should not begin with a spreadsheet of controls. It should begin with a harder operational question: can you state, with evidence, which assets support critical services, who relies on them, what is exposed, and whether the required controls are working? If the answer is uncertain, a framework programme will produce attractive documentation but limited assurance.
For regulated organisations, public-sector bodies and complex enterprises, the NIST Cybersecurity Framework is valuable because it gives cyber risk a common language. It can connect technical activity to resilience, compliance, insurance readiness and executive accountability. But the framework does not implement itself. Value comes from turning its outcomes into an operating model supported by continuous visibility and credible evidence.
Start with business services, not a control catalogue
The NIST CSF 2.0 functions - Govern, Identify, Protect, Detect, Respond and Recover - are deliberately broad. They help organisations structure decisions, but they do not prescribe a single technology stack or set of policies. That flexibility is useful, although it creates a common failure mode: teams map existing tools to framework categories and call the work complete.
A more useful starting point is the business service. Identify the services that would cause material operational, financial, safety or regulatory impact if disrupted. For each service, establish its essential applications, infrastructure, identities, data stores, suppliers and dependencies. This creates the context needed to judge risk properly.
A vulnerability on an isolated test server and the same vulnerability on a platform supporting patient care, payments or operational technology do not deserve the same response. The technical finding may be identical; the business consequence is not. NIST CSF implementation should make that distinction visible and repeatable.
Define the implementation boundary
Do not attempt to mature every area at once. Set a clear boundary for the first programme phase, such as a critical customer-facing service, an estate undergoing a regulatory review, or a high-risk cloud and identity environment.
The boundary should cover technology, people and third parties. It should also reflect where evidence can realistically be obtained. A narrow but evidenced implementation is more credible than an enterprise-wide claim that depends on manually maintained asset lists and policy attestations.
Build a current profile based on facts
The Current Profile records how the organisation meets, partially meets or does not meet relevant CSF outcomes today. Its quality depends entirely on the underlying facts. Interviews and policy reviews matter, but they are not enough. A policy stating that privileged access is reviewed quarterly is not proof that every relevant account was reviewed, removed or remediated.
Build the profile from multiple evidence sources: network and cloud discovery, identity platforms, configuration data, vulnerability records, security monitoring, change records, incident records and supplier assurance information. Reconcile differences rather than hiding them. An unmanaged asset found on the network but absent from the CMDB is not a data-quality inconvenience. It is a control gap with potential security and audit implications.
For each outcome, record three things: the level of implementation, the evidence supporting that assessment, and the owner responsible for improvement. This prevents a framework assessment becoming a one-off compliance exercise with no operational accountability.
Use evidence that can survive scrutiny
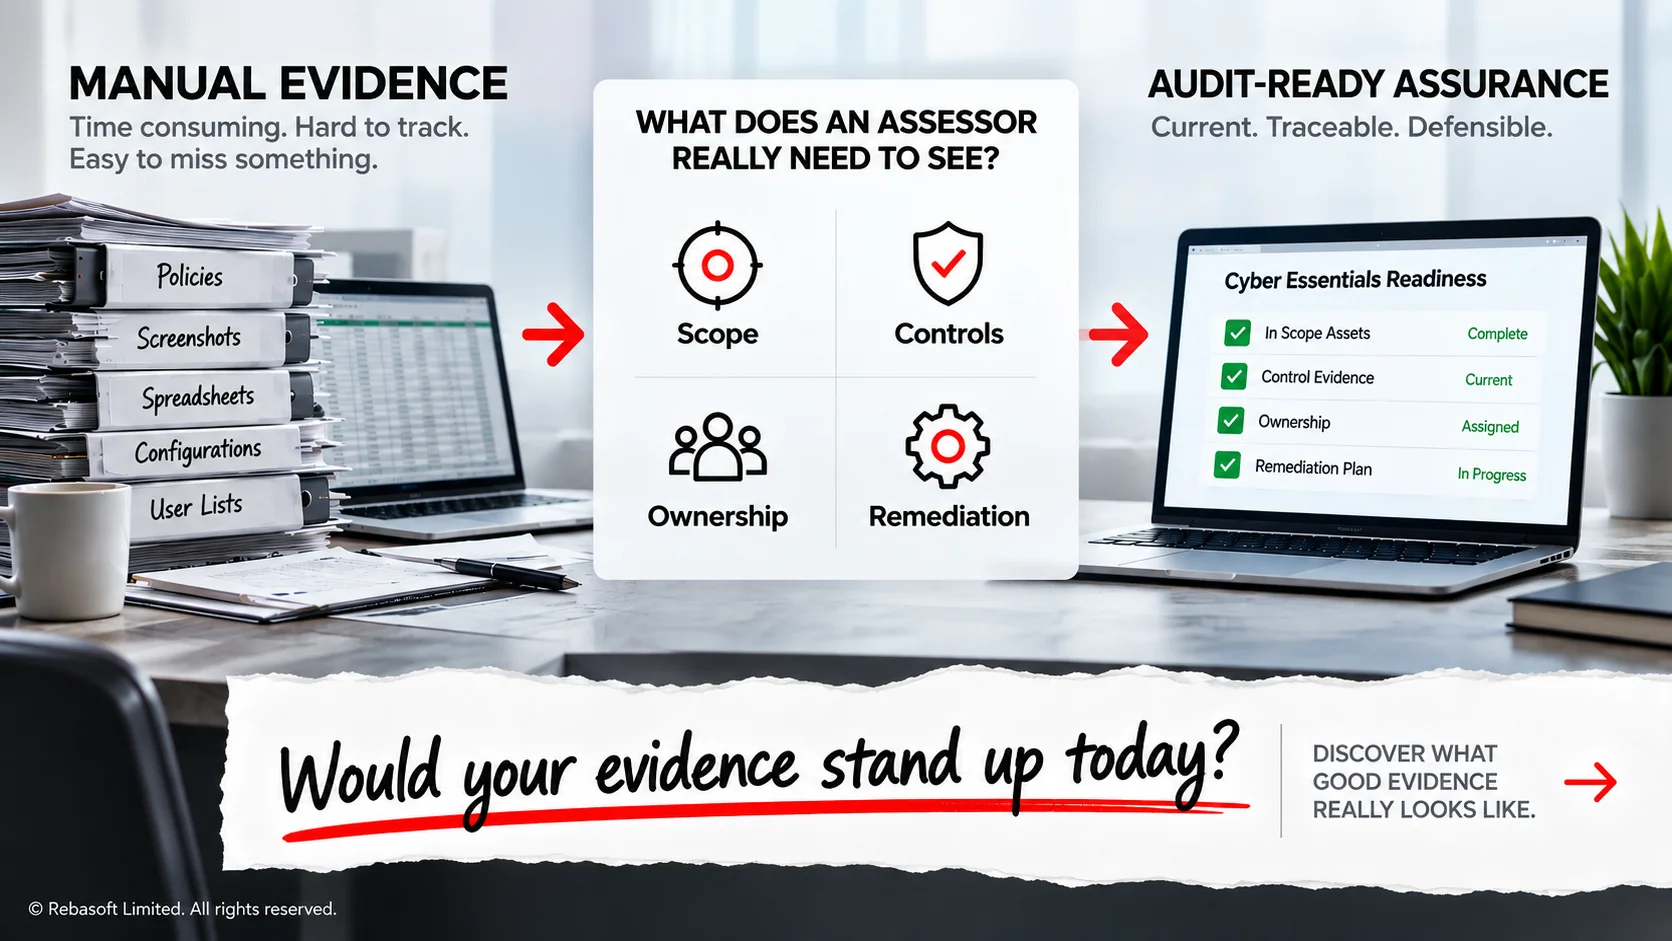
Evidence should answer a specific question and be reproducible. Screenshots can support a review, but a static screenshot has a short life. Prefer evidence that can be regenerated: current asset inventories, configuration-state reports, access review results, remediation trends and service-level risk views.
This matters during audits, but it matters even more between audits. Leadership needs answers they can trust when an incident, insurer or regulator asks what is affected. Continuous evidence reduces the time spent chasing exports across security, IT operations and compliance teams.
Create a target profile that reflects risk appetite
A Target Profile is not a wish list. It is a risk-based statement of the outcomes required to protect priority services to an agreed standard. The target should account for legal obligations, customer commitments, threat exposure, operational dependencies and the organisation's tolerance for downtime or data loss.
For example, multifactor authentication may be mandatory for all administrative access, while stronger resilience requirements may apply to systems supporting emergency response or core revenue collection. The target profile should be sufficiently specific to guide investment, without pretending every system warrants identical controls.
This is where the Govern function earns its place. Senior leaders should approve the risk appetite, priorities and ownership model, not merely receive a red-amber-green dashboard after decisions have been made. A board can reasonably accept a defined risk for a low-impact legacy system. It should not be asked to accept an unknown risk caused by incomplete asset visibility.
Prioritise gaps by service impact and exploitability
The gap between current and target profiles can be substantial. Treating every gap as equally urgent creates noise, delays remediation and erodes confidence in the programme. Prioritisation needs more than severity scores.
Assess each gap against the service it affects, internet exposure, privilege level, known exploitation, compensating controls, recoverability and likely business impact. A missing configuration baseline on a critical identity service may warrant immediate action even if no active exploit is known. Conversely, a lower-priority gap may be accepted temporarily where isolation and recovery controls are demonstrably effective.
A practical remediation plan should identify the accountable executive, operational owner, required change, due date, dependencies and evidence of closure. Avoid closing actions simply because a ticket is complete. Close them when the control state has been validated.
Where resources are limited, focus first on the gaps that reduce multiple risks at once. Accurate asset and service intelligence, identity visibility and secure configuration assurance often improve outcomes across Identify, Protect, Detect and Recover. This is usually more effective than buying another point tool that produces alerts without context.
Make the framework part of daily operations
NIST CSF is not a separate security project. It should influence how teams manage change, prioritise vulnerabilities, review access, test recovery and report risk. The best implementation work reduces operational friction because it replaces manual evidence gathering and disconnected reporting with a common view of what matters.
Set a review rhythm that matches the risk. Critical service exposure may require daily monitoring, while the profile itself may be formally reviewed quarterly or after major organisational change. Trigger-based reviews are equally important: mergers, cloud migrations, new suppliers, material incidents and significant service changes should prompt reassessment.
Measures should be meaningful to both operational and executive audiences. Track coverage of discovered assets, unmanaged identities, critical control exceptions, time to remediate high-impact exposures, evidence freshness and resilience test outcomes. Then translate those measures into service risk: which critical services remain outside the agreed assurance level, and what decision is required?
Avoid the common implementation traps
Three mistakes repeatedly undermine NIST CSF programmes. The first is treating the framework as a compliance crosswalk rather than a risk management method. A crosswalk can show coverage; it cannot prove that controls work in the environment that matters.
The second is relying on a CMDB or asset register as the sole source of truth. These sources are useful, but fast-changing estates create drift. Discovery must validate what is actually connected, configured and exposed.
The third is producing board reports that show control status without business context. Executives do not need every technical exception. They need to understand the material services at risk, the decisions needed, the cost of delay and the evidence behind the assessment.
An integrated assurance platform such as Rebasoft can support this model by bringing asset, identity, configuration, vulnerability and service intelligence into one evidence base. The point is not to force every activity through one product. It is to reduce fragmented tooling and give technical teams and leadership a shared, current view of risk.
Treat assurance as a capability, not a deadline
A successful NIST CSF implementation changes the quality of decisions. Security teams spend less time reconciling inventories and assembling audit packs. IT teams can focus remediation on the services that matter most. Leaders receive evidence they can use to direct investment and accept risk consciously.
The framework becomes most valuable when it is tested by real operational questions: What changed? What is exposed? Which service is affected? Is the control working? Who owns the response? Build the ability to answer those questions continuously, and the framework will support resilience long after the initial assessment is complete.